Sonnet 5.5 and Sol 6.1 move Saggar's defaults again
GPT-6.1 Sol now powers Saggar's Codex Everyday and Hard recommendations. Sonnet 5.5 has the highest score on Bug Hunt Bench at max, but its cost and runtime keep Opus 5.5 in Everyday for Claude.
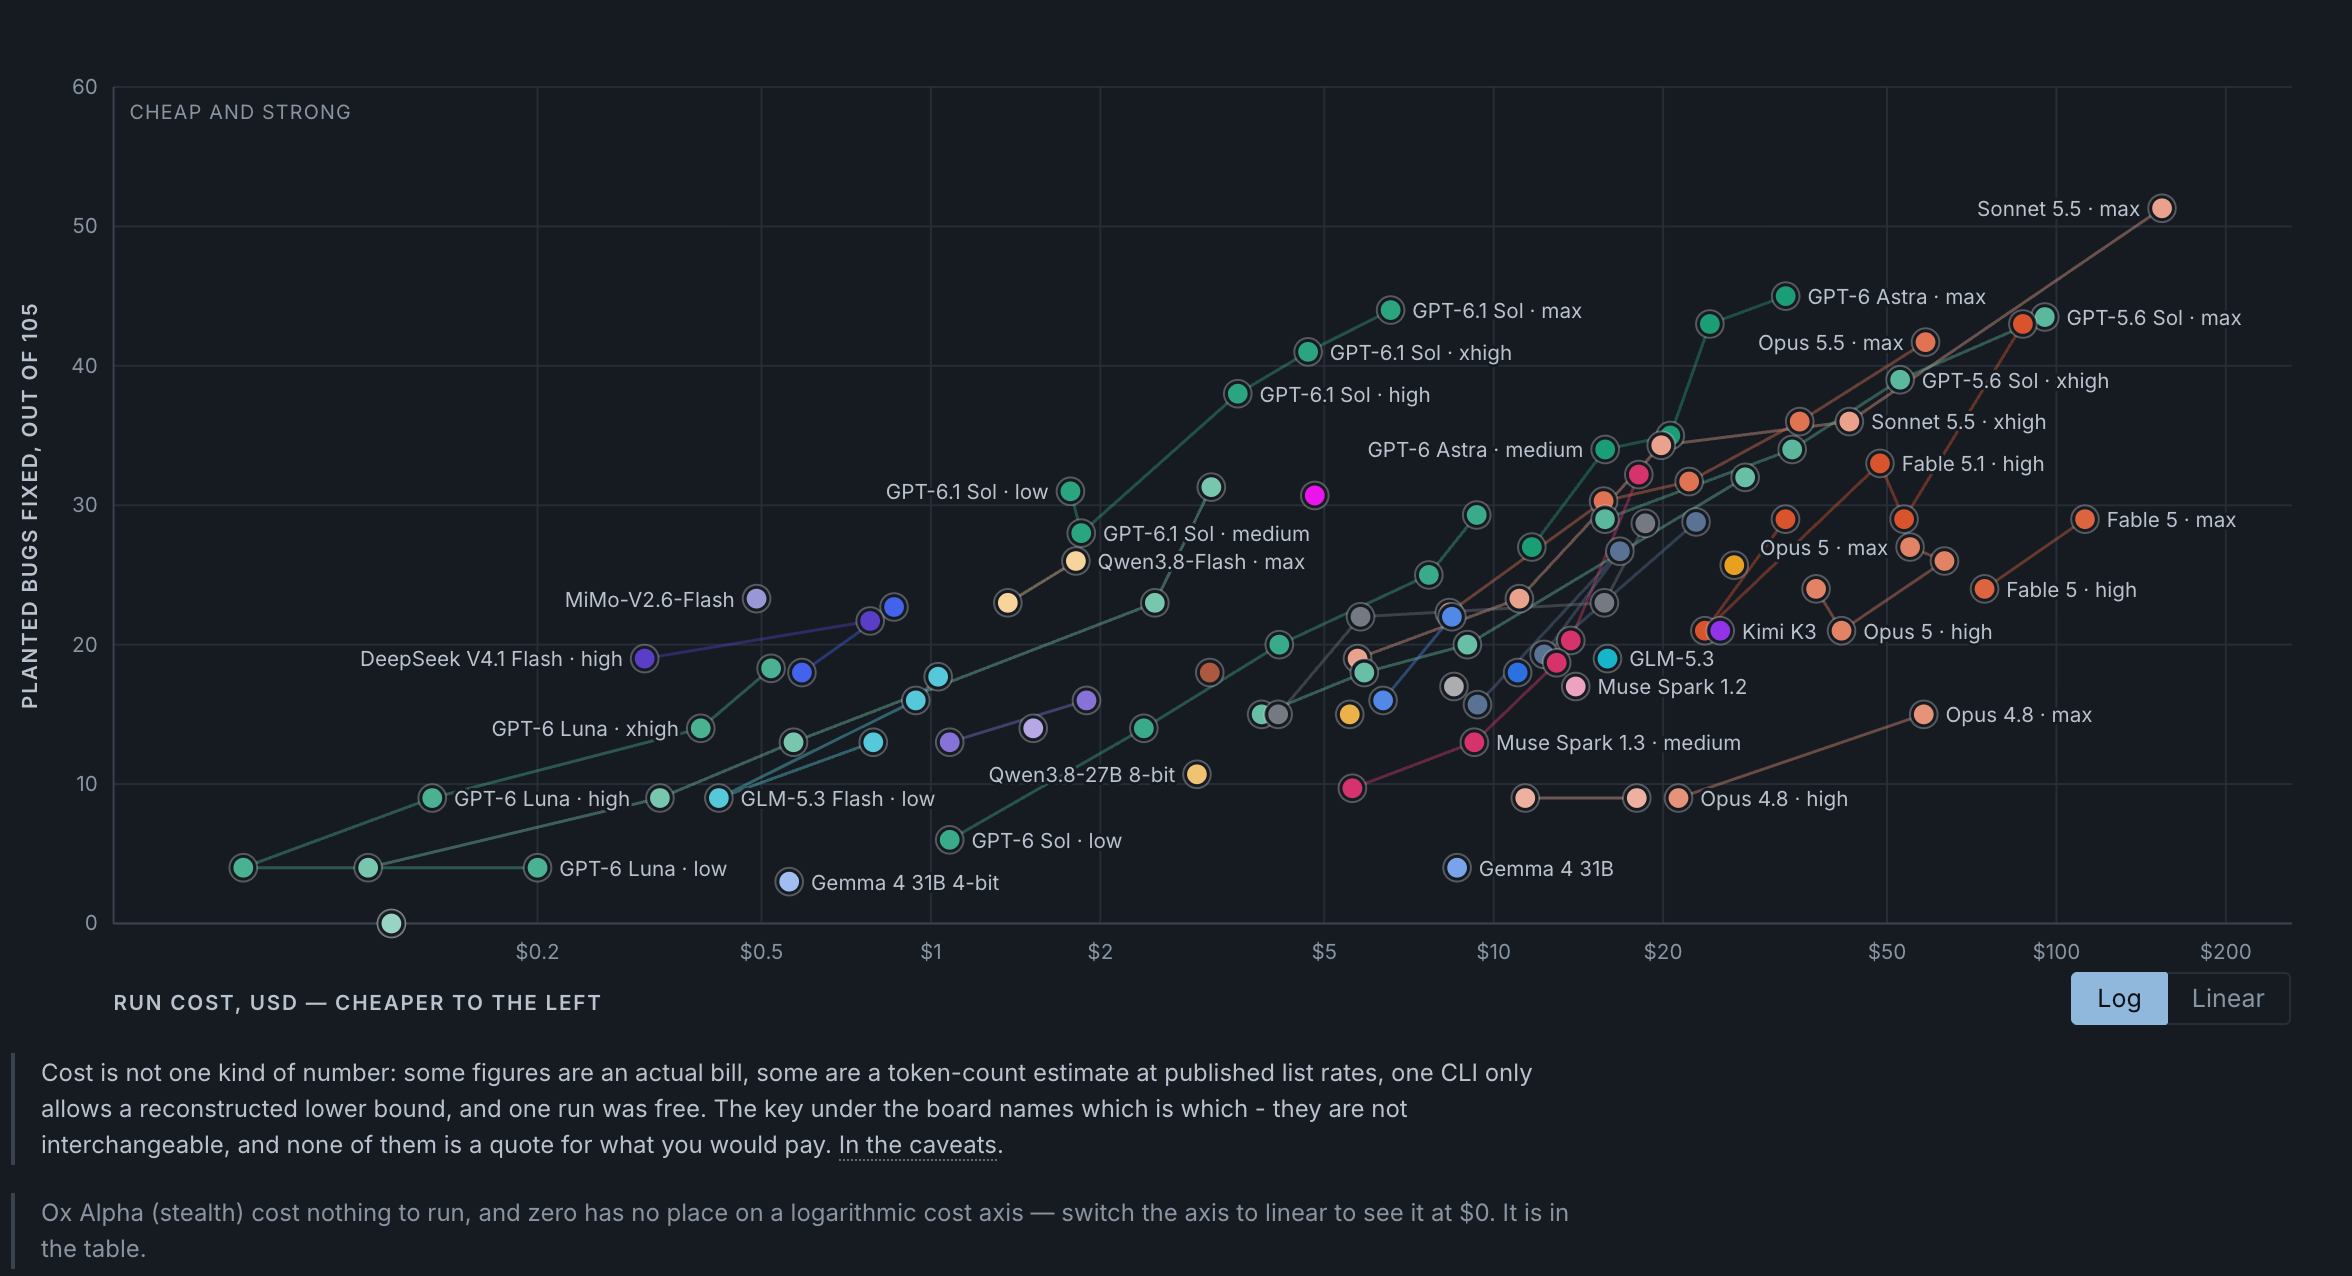
GPT-6.1 Sol now powers Saggar's Codex Everyday and Hard recommendations. Sonnet 5.5 has the highest score on Bug Hunt Bench at max, but its cost and runtime keep Opus 5.5 in Everyday for Claude.
If you run lots of agents in parallel, sooner or later they all start a build or a test suite at the same moment, and your Mac grinds to a halt. turnstile might help.
Saggar now starts each Codex and Claude model on its own default effort, chosen for the best balance of results, cost, and time, rather than the provider's blanket default.
A screenshot is often the shortest useful prompt you can give a coding agent. It captures spacing, hierarchy, density, clipping, and the exact state of the interface in one artifact.
Anthropic's advice for getting more from Claude Code sessions comes down to one rule: keep each context small and relevant.
Saggar is built around one question: which terminal needs you right now?